Li Bo (李博)
About Me
I am Li Bo (李博), a master’s student in Computer Technology at the School of Computer Science and Engineering, Sun Yat-sen University. I received my B.S. degree in Computer Science and Technology from Sun Yat-sen University in 2025, with a GPA of 4.05 and a recommendation for graduate study.
My research focuses on how to make learning systems acquire new capabilities without erasing what they already know. I am currently interested in LLM post-training, on-policy distillation, Agentic RL, long-horizon coding agents, source-free domain adaptation, and multimodal learning.
Research Interests
- LLM Post-training: supervised fine-tuning, knowledge distillation, preference optimization, and reinforcement learning
- Capability Preservation: bounded suppression, retention and acquisition evaluation, and continual capability integration
- Agentic Learning: long-horizon coding agents, task-state modeling, tool use, verifier-guided RL, and multi-turn rollouts
- Multimodal Learning: source-free domain adaptation, multi-video perception, and evidence-grounded reasoning
Research in Progress
Learning Without Erasure: Bounded Suppression for On-Policy Distillation
First author · 2026.06 - present
This project studies the Suppression-First Bias that can arise when on-policy distillation integrates capabilities across stages or experts. The ongoing work develops PRESERVE-OPD, a bounded suppression framework that combines ASA suppression-gradient annealing with an RBTP student reference and a token-level forgetting budget. The evaluation separates capability Retention, Acquisition, and UnionGap.
News
- [Aug. 2026] COSMO is available on arXiv and is under review at AAAI 2027.
- [Jun. 2026] Started work on capability preservation for on-policy distillation.
- [May 2026] Started PolicyForge, a long-horizon coding-agent post-training project.
Publications
-
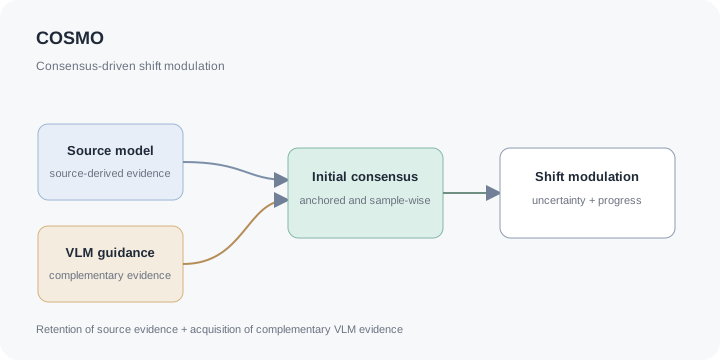 arXiv
arXiv preprint arXiv:2608.04604, 2026. Under review at AAAI 2027.PDF Project Page First author
Projects
PolicyForge: State Understanding for Long-horizon Coding Agents
2026.05 - 2026.08 · SWE-Gym · OpenHands · Qwen3 · SFT · On-Policy Distillation · GRPO / RLVR
- Audited trajectories to separate tool-protocol errors, loop deadlocks, termination-state mistakes, and task-semantic failures.
- Action-Aware SFT reduced the loop-deadlock rate from 59% to 17% and increased the valid-termination rate from 20% to 58%.
- Structured Task Belief modeling improved task success on Core-100 from 8% to 18%; verifier-guided asynchronous GRPO reached 26%.
UnicVR: Multi-video Active Perception and Multi-agent Collaborative Post-training
2026.03 - 2026.06 · Reasoner · Perceptioner · structured evidence · role-level SFT
- Designed a Reasoner-Perceptioner architecture that chooses single-view observation, parallel observation, cross-video comparison, or final answering according to the current hypothesis and visual budget.
- Built compact working memory for candidate answers, verified evidence, unresolved questions, and remaining budget.
- Converted collaborative trajectories into role-specific supervision for more effective evidence acquisition and termination.
Education & Experience
- 2025.09 - 2028.06 · Sun Yat-sen University, M.S. in Computer Technology, School of Computer Science and Engineering, Guangzhou
- 2021.09 - 2025.06 · Sun Yat-sen University, B.S. in Computer Science and Technology, School of Computer Science and Engineering, GPA 4.05, Guangzhou
- 2024.11 - 2025.03 · ByteDance / Volcano Engine, Recommendation Architecture - Data Warehouse Development Intern
- Built real-time and offline recommendation-data pipelines with Flink, Spark, Kafka, and Hive.
- Designed downstream Diff attribution and Baseline-Test validation for heterogeneous migrations involving IndexService, MongoDB, Redis, and Kafka.
Honors & Awards
- National Scholarship
- First-class Academic Scholarship (top 2%)
- Second Prize, National College Mathematics Competition
- Second Prize, Mathematical Contest in Modeling (MCM / ICM)
Skills
- Programming: Python, PyTorch, C / C++, Java; CCF-CSP Top 1.5%
- LLM post-training: SFT, knowledge distillation, preference optimization, PPO, GRPO, Reward Model, Verifier, multi-turn rollout, and Agentic RL
- Systems: veRL, vLLM, SGLang, Flink, Spark, Kafka, and Hive
- Language: CET-6 (567); academic reading, technical documentation, and research writing
Powered by Jekyll and Minimal Light theme.